

Sometimes You Gotta Run Before You Can Walk: Run-then-Walk Scheduling Strategy for VLM Autonomous Driving
Paper • 2609.25831 • Published
AutoDrive-P3 Paper · Run-then-Walk Paper · Source Code · Checkpoints and Data
This Hugging Face repository releases the SFT, Run-stage, and Walk-stage checkpoints and NAVSIM train/test JSON annotations for AutoDrive-P3 with Run-then-Walk. The models are based on Qwen2.5-VL-3B-Instruct. Training, data processing, inference, and evaluation code are available in the GitHub repository.
The release connects two papers:
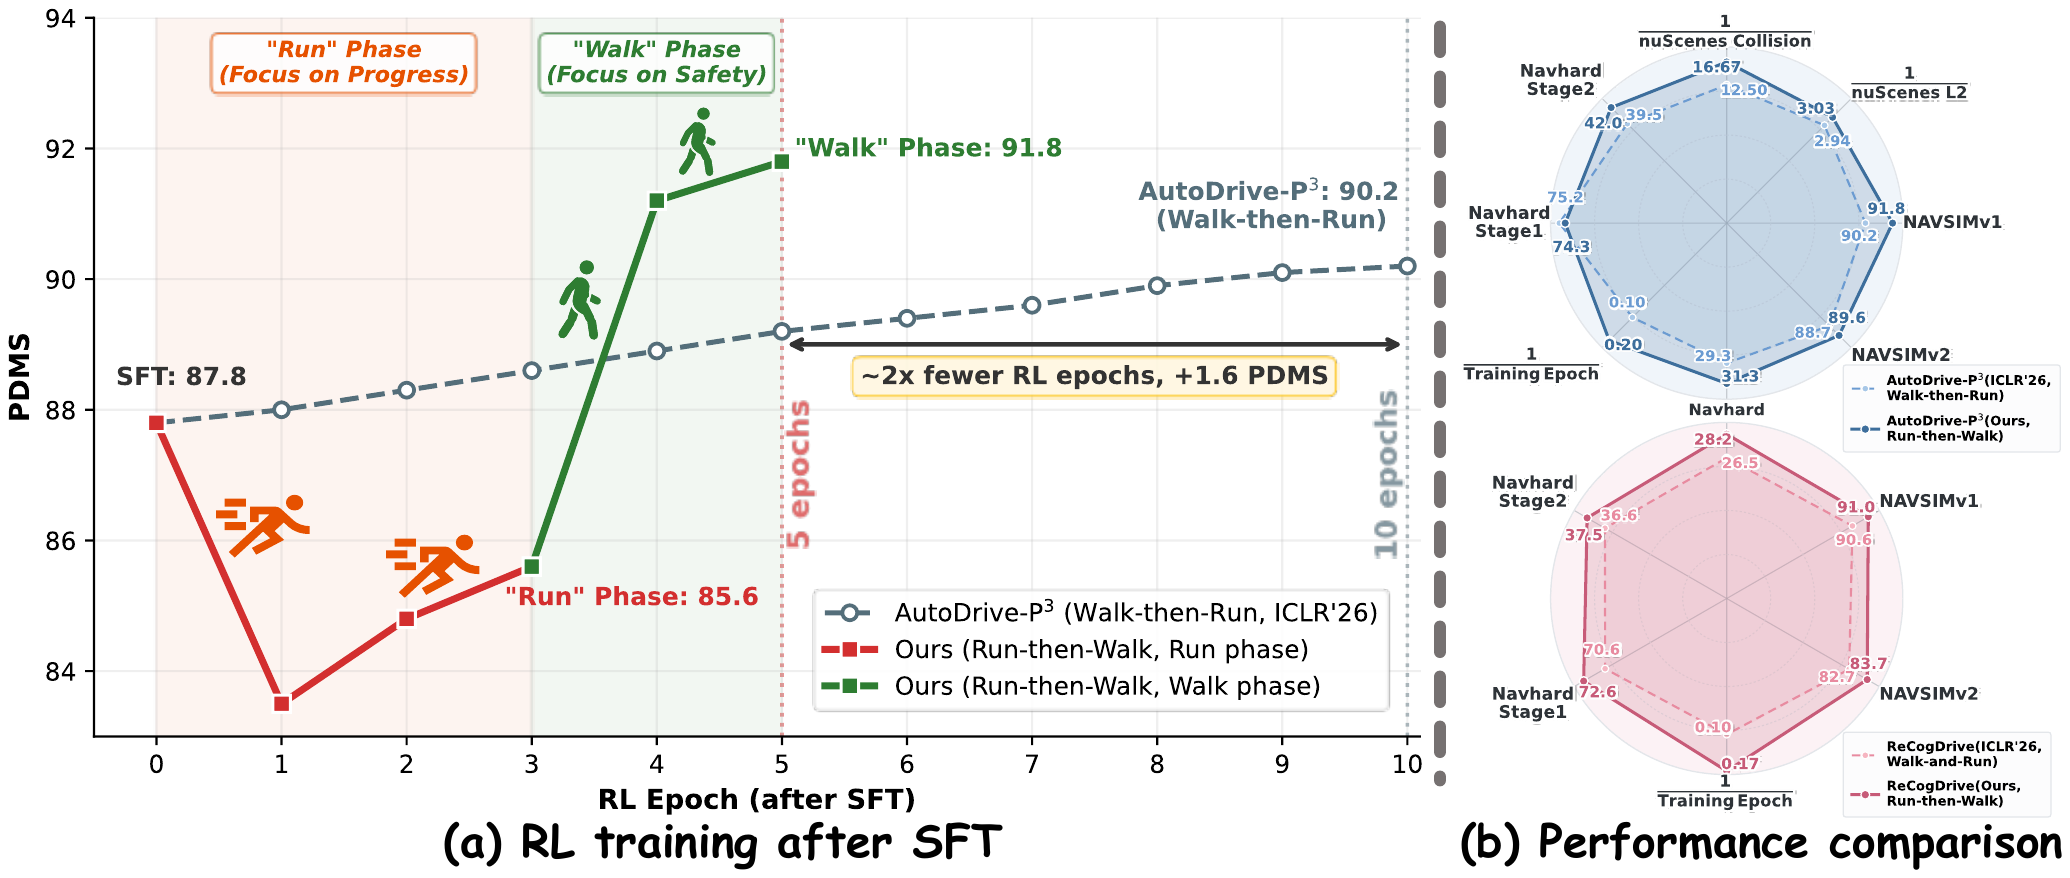
Starting from the SFT policy, the Run stage uses a PDMS planning reward to discover trajectories with greater progress. The Walk stage then uses endpoint and DAC/TTC safety feedback to improve their safety while preserving progress. The final Walk checkpoint achieves 91.8 PDMS on NAVSIM v1 in the reported fast-mode evaluation.
| Directory | Training stage | NAVSIM v1 PDMS |
|---|---|---|
| SFT/ | Supervised fine-tuning; starting policy for Run-then-Walk | 87.8 |
| RL_stage1_run/ | First RL stage: Run, using the PDMS reward | 85.7 |
| RL_stage2_walk/ | Second RL stage: Walk, using endpoint and DAC/TTC safety feedback | 91.8 |
Use RL_stage2_walk/ for the final Run-then-Walk policy. RL_stage1_run/ is an intermediate policy: its greater progress is accompanied by weaker safety metrics, which the Walk stage addresses. The follow-up study reports three Run epochs followed by two Walk epochs.
Each checkpoint directory contains sharded safetensors weights, config.json, a weight index, and the tokenizer, processor, chat-template, and generation files. Download an entire checkpoint directory to keep these files together.
These scores are reported in the accompanying Run-then-Walk study and GitHub checkpoint table. The original AutoDrive-P3 paper reports 90.2 PDMS with its Walk-then-Run schedule; the RL directories here contain the follow-up Run-then-Walk stages.
The Data/ directory contains:
| Files | Split | Image resolution |
|---|---|---|
1_RL_train_672_168.json, 1_RL_test_672_168.json |
Train and test | 672 × 168 |
1_RL_train_2048_512.json, 1_RL_test_2048_512.json |
Train and test | 2048 × 512 |
These JSON files provide annotations for the AutoDrive-P3 data-processing pipeline. The public scripts default to 672 × 168 and construct four-frame history videos at 2 FPS. Model responses contain structured <perception>, <prediction>, and <planning> sections; planning uses eight future ego-local [x, y, heading_radians] points at 0.5-second intervals.
Prepare raw NAVSIM logs, camera sensor blobs, and maps separately. Official PDMS evaluation also requires NAVSIM metric caches. Follow the data-processing instructions to build the processed datasets used by the source code.
Install the Hugging Face Hub client:
pip install huggingface_hub
Download the final checkpoint and the default-resolution annotations:
from huggingface_hub import snapshot_download

snapshot_download(
    repo_id="yuki-hahaha/AutoDrive-P3_with_Run-then-walk",
    local_dir="../models/AutoDrive-P3_with_Run-then-walk",
    allow_patterns=["RL_stage2_walk/**", "Data/*_672_168.json"],
)
To download another stage, replace RL_stage2_walk/** with SFT/** or RL_stage1_run/**. Use Data/*.json to download both annotation resolutions.
Clone the code and install its SFT/RL dependencies as described in the GitHub README:
git clone https://github.com/haha-yuki-haha/AutoDrive-P3_with_Run-then-walk.git
cd AutoDrive-P3_with_Run-then-walk
Run the download snippet above from this source checkout to place the model repository at ../models/AutoDrive-P3_with_Run-then-walk. Copy the default-resolution annotations to the layout expected by the data pipeline:
mkdir -p ../data/AutoDrive_P3
cp ../models/AutoDrive-P3_with_Run-then-walk/Data/1_RL_train_672_168.json ../data/AutoDrive_P3/
cp ../models/AutoDrive-P3_with_Run-then-walk/Data/1_RL_test_672_168.json ../data/AutoDrive_P3/
export AUTODRIVE_P3_ROOT=../data/AutoDrive_P3
After preparing the processed test dataset, generate a prediction using the final checkpoint:
python inference/generate_json.py \
  --model-path ../models/AutoDrive-P3_with_Run-then-walk/RL_stage2_walk \
  --dataset-dir ../data/RL_processed_dataset_test \
  --output-json outputs/final_results.json \
  --index 0
The command generates one sample; it does not run the complete benchmark. The helper defaults to two-way tensor parallelism. Add --tensor-parallel-size 1 when running on one GPU with sufficient memory.
Evaluate the prediction with an official NAVSIM metric cache:
python inference/calculate_pdms.py \
  --prediction-json outputs/final_results.json \
  --metric-cache ../data/navsim/metric_cache \
  --output-json outputs/pdms.json
See the inference and evaluation guide for the video input format, model dependencies, and evaluation settings. Run-stage and Walk-stage training recipes are documented in the source repository.
This model repository is tagged with the Apache 2.0 license. The Qwen2.5-VL backbone and NAVSIM data retain their respective terms.
Please cite the relevant papers when using the models, annotations, or training method:
@inproceedings{ye2026autodrivep3,
  title={AutoDrive-P3: Unified Chain of Perception-Prediction-Planning Thought via Reinforcement Fine-Tuning},
  author={Ye, Yuqi and Zhang, Zijian and Lin, Junhong and Sun, Shangkun and Peng, Changhao and Gao, Wei},
  booktitle={The Fourteenth International Conference on Learning Representations},
  year={2026},
  url={https://openreview.net/forum?id=CMU8GxwpUL}
}

@article{ye2026sometimes,
  title={Sometimes You Gotta Run Before You Can Walk: Run-then-Walk Scheduling Strategy for VLM Autonomous Driving},
  author={Ye, Yuqi and Sun, Shangkun and Lin, Junhong and Zhao, Jiayi and Peng, Changhao and Zheng, Wei and Liu, Guoqing and Zhao, Tiesong and Gao, Wei},
  journal={arXiv preprint arXiv:2609.25831},
  year={2026},
  url={https://arxiv.org/abs/2609.25831}
}
Contact: Yuqi Ye. Driving demonstrations are available in the GitHub README.
Base model
Qwen/Qwen2.5-VL-3B-Instruct