PAGE: Parts-Aware Guidance for Co-Speech Gesture Portrait Video Generation
Paper • 2610.13301 • Published
This is the Chinese Announcer Speech (CAS) dataset proposed in our paper [TCSVT 2026] PAGE: Parts-Aware Guidance for Co-Speech Gesture Portrait Video Generation.
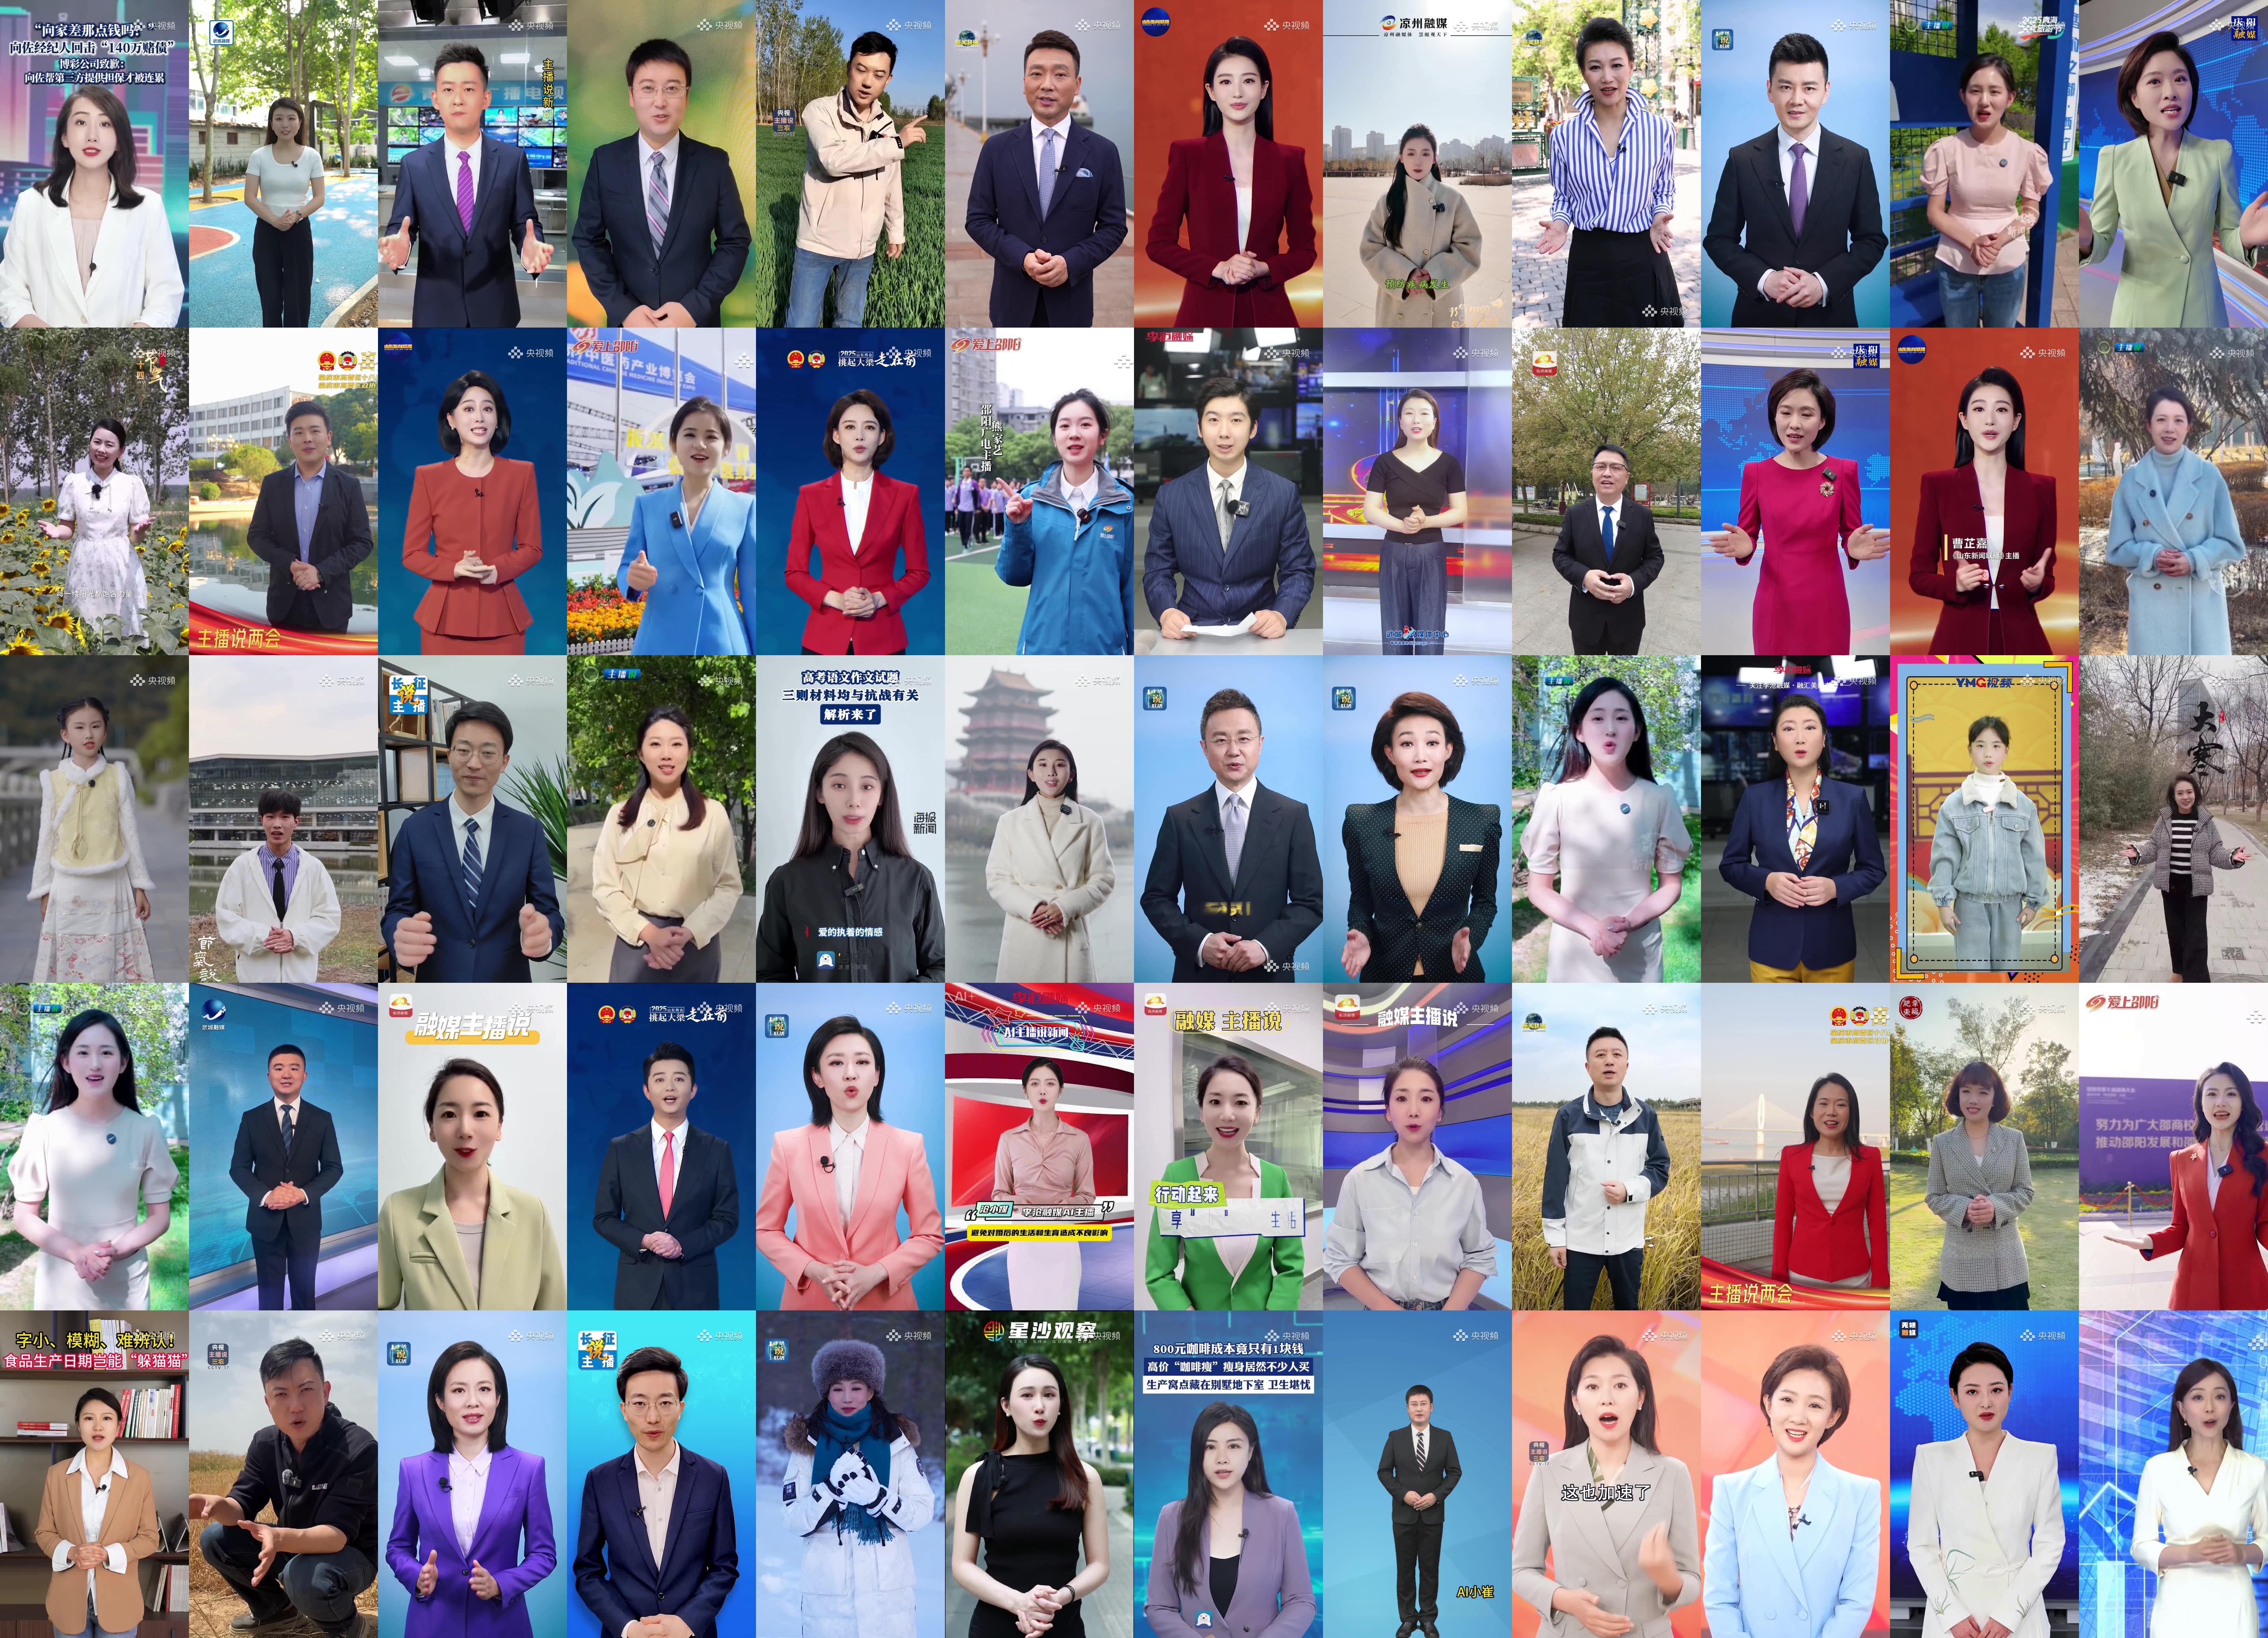
The CAS dataset is a large-scale dataset designed for the evaluation of co-speech gesture portrait video generation. It contains over 19,000 video clips featuring more than 800 unique speakers, covering diverse scenarios, camera views, body poses, and expressive speaking styles.
CAS encompasses a broad range of real-world speaking scenarios, including indoor and outdoor environments, full-body and half-body framing, standing and seated postures, and diverse expressive speaking styles. These characteristics make CAS a valuable benchmark for evaluating the visual quality, motion diversity, and generalization capabilities of co-speech gesture portrait video generation methods.
You can download the dataset using the official Hugging Face Python library (huggingface_hub) or the Hugging Face CLI (hf).
After downloading, you should have 33 split archive files, named CAS.tar.001 through CAS.tar.033. To extract the dataset, run:
cd data/
cat CAS.tar.0* | tar -xvf -
After extraction, the dataset directory will have the following structure:
CAS/data
├── test_audio/
├── test_video/
├── train_audio/
└── train_video/
📌 If you find our work helpful, please consider citing our paper. Thank you!
@article{Wang2026PAGE,
    author    = {Yabiao Wang and Jiafu Wu and Yicheng Xu and Teng Hu and Shengzhe Zhou and Yanxiao Sun and Jiangning Zhang and Ying Tai and Yong Liu and Ming-Hsuan Yang},
    title     = {PAGE: Parts-Aware GuidancE for Co-Speech Gesture Portrait Video Generation},
    journal   = {IEEE Transactions on Circuits and Systems for Video Technology (TCSVT)},
    year      = {2026},
    volume    = {},
    number    = {},
    pages     = {},
    doi       = {10.1109/TCSVT.2026.3738661}
  }